GPU First For Developers: Gemma <12GB, Llama 3 40GB+
If you need an efficient, local, multimodal model that runs on modest hardware, start with Gemma. If you need the largest open-weight coding and production ceiling, start with Llama. Smaller Gemma checkpoints often edge out similarly sized Llama models on instruction following, while Llama 70B variants tend to win on coding accuracy. Your GPU budget and modality needs should decide the rest.
TL;DR:
- Gemma models generally excel in instruction-following and native multimodal input, making them better suited for hardware-constrained environments with image input needs.
- Llama models, especially the 70B variants, outperform Gemma on coding accuracy benchmarks and have a deeper ecosystem for fine-tuning and inference tools.
- Hardware resources limit model choice more than model size, with smaller Gemma and Llama models fitting single consumer GPUs under 24GB VRAM, while larger Llama models need multi-GPU setups.
- Benchmark results indicate Gemma narrows the reasoning gap with larger Llama models at intermediate sizes, but Llama still leads in code-generation accuracy at larger scales.
- Licensing differences mean Gemma's terms vary by model card, while Llama’s community license carries usage restrictions, making licensing review important before deployment.
Table of Contents
- Which model checkpoints should you shortlist first?
- What the benchmarks actually tell you about each family
- Matching your hardware tier to the right model
- A checklist for choosing and validating your model
- What running local models on everyday hardware actually looks like
- Our recommendation for developers weighing both families
- A private, offline option if you'd rather skip the setup
- Where these figures and claims come from
- Sources
- FAQ
Not sure your PC is up to it? Check what runs on yours
Which model checkpoints should you shortlist first?
Before benchmarking anything, narrow your list to two or three checkpoints that match your hardware and task. Here is what each one is actually good for.
- Gemma 3 4B: best for hardware-constrained local agents that need native image input, runs comfortably on consumer GPUs.
- Gemma 3 27B Instruct: best for workstation-level deployments that need stronger reasoning without jumping to a huge Llama tier.
- Gemma 4: Google DeepMind's newer family spanning 12B to 31B tiers, aimed at local-to-enterprise multimodal work with a documented model card.
- Gemma 2: an earlier generation, still useful for low-resource experiments and older devices.
- Llama 3.2 3B Instruct: a small instruct-tuned checkpoint built for lightweight local inference with deep community tooling.
- Llama 3.2 (3B): functionally similar to the checkpoint above, valued mainly for its mature quantization recipes.
- Llama 3: the large variant that leads on coding and complex reasoning when you have server-scale infrastructure, documented in Meta's model cards.
- Llama 3.3 Instruct 70B: a heavier instruct tier for production reasoning workloads that can justify multi-GPU or high-VRAM hosting.
Gemma checkpoints tend to ship with native multimodal support built in, so you skip the extra vision encoder most Llama setups still need. Licensing differs too: Gemma ships under its own vendor terms detailed in each model card, while Llama uses Meta's community license, which carries its own redistribution rules worth reading before you deploy commercially.
What the benchmarks actually tell you about each family
Numbers only matter when they map to your task, so treat these as pointers rather than a scoreboard. On instruction-following benchmarks, Gemma 3 4B scored very well on IFEval, edging out a larger Llama 3.1 70B model in one aggregation, a reminder that model size does not guarantee better instruction adherence. Coding tells a different story: aggregated testing shows Llama 3 70B tends to perform better on code-generation accuracy benchmarks, which makes it a reasonable default for code-generation work where correctness matters more than footprint.
Gemma 4's own model card reports strong MMLU Pro, GPQA, and LiveCodeBench results across its 12B to 31B tiers, suggesting the newer family narrows the reasoning gap with larger Llama checkpoints while staying lighter to host.
A few dimensions to weigh before you commit:
- Context window: vendor model cards report context windows up to 128K or 256K tokens, but actual serving endpoints may have lower limits — verify the endpoint limits.
- Multimodal input: Gemma 3 and Gemma 4 checkpoints handle images natively in a single pass, which simplifies pipelines that would otherwise need a separate vision model bolted onto Llama.
- Hardware footprint: quantized Gemma 3 4B and Llama 3 8B models use similar VRAM amounts on consumer GPUs, so size alone will not tell you which one to pick.
- Ecosystem maturity: Llama has the deeper library of fine-tuning recipes and inference integrations across llama.cpp, vLLM, and Ollama, largely because it has been public longer.
- Licensing: Llama's community license carries usage and redistribution conditions worth reading closely; Gemma's terms live in each model card and vary slightly by generation.
Independent comparisons converge on the same split: Gemma for hardware-efficient local and multimodal work, Llama for ecosystem depth and coding-heavy production.
Matching your hardware tier to the right model
Your GPU, not your ambition, should decide which checkpoint you try first.
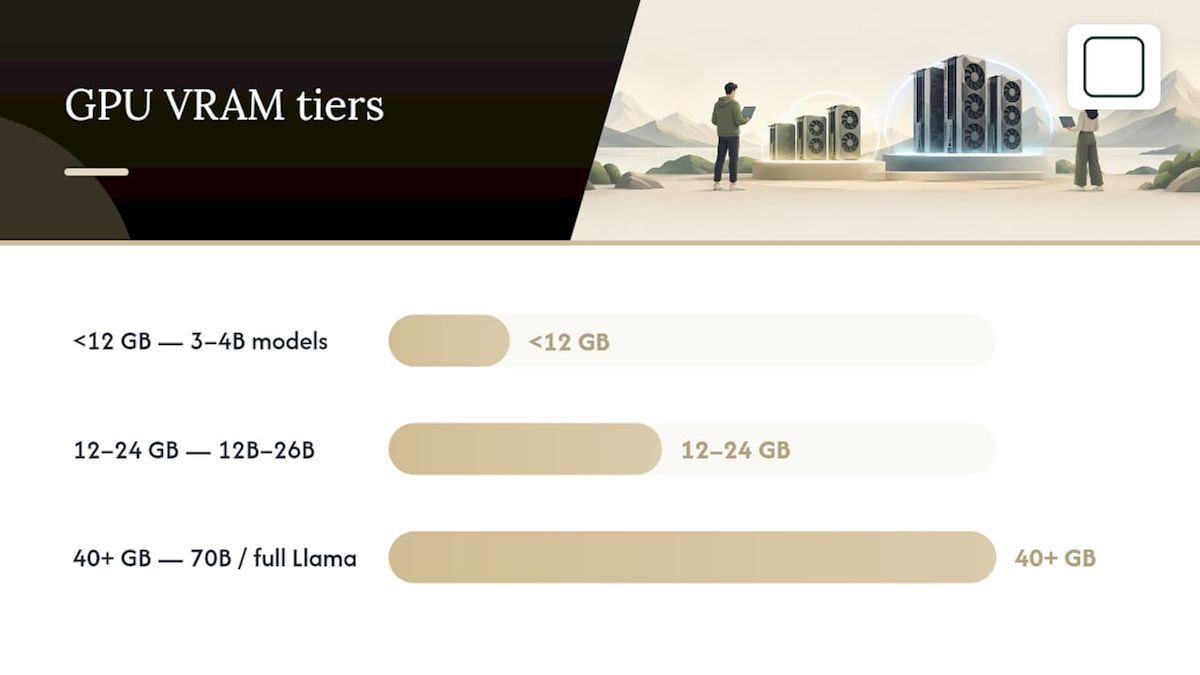
- Single consumer GPU under 12GB of VRAM: stick with smaller Gemma tiers like Gemma 3 4B or a similarly sized Llama 3.2 3B Instruct build.
- 12 to 24GB of VRAM: quantized 12B to 26B options, including Gemma 3 27B Instruct at reduced precision, become workable.
- 40GB or more on a single card: this is where Llama 3.3 Instruct 70B or full Llama 3 checkpoints start to make sense.
- Multi-GPU setups: reserve these for the largest Llama tiers when your workload genuinely needs that reasoning ceiling.
Quantized 4-bit builds cut memory needs substantially compared to full precision, though throughput drops as you push quantization further, so test actual tokens-per-second on your own card rather than trusting a spec sheet. Before committing infrastructure budget, run a short checklist: sample prompts from your real workload, a target throughput number, an acceptable latency ceiling, and, for code tasks, a rough cost-per-correct-completion so you're comparing accuracy against spend, not just raw speed.
Pro Tip: Benchmark on your actual hardware before buying more GPU. A quantized 4B model that hits your accuracy bar beats an unquantized 27B model you can't run at production latency.
A checklist for choosing and validating your model
Pick criteria in order of what actually blocks deployment, not what looks impressive on a leaderboard.
- Hardware fit first: if it does not run on what you have, nothing else matters.
- Modality needs next: confirm whether you need native image or audio input before comparing text-only scores.
- Task accuracy on benchmarks relevant to your workload, not aggregate scores.
- Fine-tuning requirements and whether your target framework supports the checkpoint you want.
- Ecosystem integration with your existing inference stack.
- License terms for your specific commercial use case.
Once your shortlist is set, validate it in order:
- Run a small workload test on representative prompts.
- Check code correctness against a held-out test set if coding matters to you.
- Test retrieval integration if the model feeds a RAG pipeline.
- Scale up and measure cost at the volume you actually expect.
Watch for red flags along the way: no quantized build available for your hardware, licensing language that is vague about commercial redistribution, or a missing model card with no published benchmarks at all. Any of those should push a checkpoint down your list regardless of how it performs in a demo.
What running local models on everyday hardware actually looks like
GreenCube runs entirely offline on Windows and downloads one local model the first time you set it up. At that setup step, you pick between two presets built on the model families covered here: a fast plain-text option with a smaller download, and a larger version that reads images and builds study guides but requires more RAM and runs slower.
- Smaller downloads answer faster but do not handle image input, reflecting the Llama 3.2 3B model's capabilities.
- The larger Gemma 4 E4B preset needs more RAM and patience but handles documents a plain-text model cannot.
- Neither preset replaces a large cloud model for extreme reasoning tasks, and that gap is real and worth planning around.
Pro Tip: If your computer struggles with the larger preset, that is a hardware signal, not a software problem: try the smaller model first and upgrade your expectations to match your machine.
Our recommendation for developers weighing both families
Pick Gemma when your binding constraint is hardware or when you need native multimodal input without extra plumbing. Pick Llama when coding accuracy or ecosystem depth matters more than footprint, and you have the infrastructure to host a larger checkpoint. Pilot small before you invest in bigger GPUs: a quantized 4B or 3B model that clears your accuracy bar on real prompts is worth more than a theoretical leaderboard win you can never run at acceptable latency.
— Hector Gras
A private, offline option if you'd rather skip the setup
Everything above assumes you're comfortable running llama.cpp, Ollama, or vLLM yourself and picking checkpoints by hand. If you'd rather have someone hand you a working setup, GreenCube packages Gemma model builds into a downloadable Windows app for a one-time purchase, with no subscription and no server involved.
- Chats and documents stay on your machine; only the features you turn on ever touch the internet.
- Setup asks for a one-time Google or Microsoft sign-in just to check your license, nothing else leaves your device.
- Works well for privacy-conscious professionals, students who need offline study tools, and anyone handling sensitive documents who does not want them uploaded anywhere.
It suits people who want a private assistant without configuring an inference stack, more than developers already comfortable running raw checkpoints. If that's you, get GreenCube and it picks the model for your PC on first launch.
Where these figures and claims come from
- LLM Stats aggregated benchmark comparisons for IFEval and coding scores across both families.
- Gemma 4 model card and Gemma 3 model card for vendor-reported benchmarks and context windows.
- Meta's Llama 3 model cards for sizing and prompt format details.
- Faun for independent framing on use-case fit.
For related decision frameworks, see how these models compare to other LM Studio alternatives, how to weigh Ollama against LM Studio for your inference stack, or a broader look at choosing small LLMs by hardware instead of leaderboard rank. If you're still deciding between local ownership and a cloud subscription, this piece on local AI versus ChatGPT covers that tradeoff directly. This roundup of local AI alternatives covers adjacent tools worth knowing about.
FAQ
Is Gemma better than Llama?
Neither family wins universally: Gemma checkpoints often lead on instruction-following benchmarks and native multimodal support, while Llama 70B variants tend to score higher on coding tasks. The right choice depends on your hardware limits and whether your workload leans toward reasoning, coding, or image input.
Is Gemma 3 free to use?
Gemma 3 model weights are available for download under Google's own model terms, which you can review directly in each model card before committing to a commercial use case. Costs come from the hardware you run it on, not a licensing fee for the model itself in typical use.
Is Google Gemma the same as Gemini?
No, Gemma and Gemini are different products from Google. Gemma is a family of open-weight models you can download and run yourself, including on local hardware, while Gemini is Google's cloud-hosted assistant accessed through Google's own apps and APIs.
Which Gemma is best for coding?
Among the checkpoints covered here, Gemma 4's 12B to 31B tiers report strong LiveCodeBench results on their vendor model card, making that family a reasonable Gemma option for coding work. For workloads where coding accuracy is the top priority above everything else, aggregated testing still shows larger Llama checkpoints holding an edge on coding-specific benchmarks.
Recommended
- Ollama vs LM Studio: A Developer's Comparison Guide
- Choose by Hardware, Not Leaderboards: Best Small LLM for Local Use
- Ollama in 6 Commands for Developers: Run a Local LLM and Avoid Pitfalls
- Best Local AI Models by Hardware Tier in 2026
Will GreenCube run on your PC?
- Seed8 GB of RAM, no graphics cardEverything works, just slower.
- Sprout16 GB of RAM, or 8 GB with a cardSteady speed, writes slide decks.
- BloomA graphics card with 8 GB, or a 4-6 GB card with 16 GB of RAMFast, pictures with no waiting.
- ThriveA card with 8 GB or more and 24 GB of RAM or moreThe fastest.
GreenCube looks at your PC and sets up the AI model that fits it: no terminal, no settings. €9.99 (US$9.99), paid once, and it's yours.